Index
Contents
arXiv

TL;DR
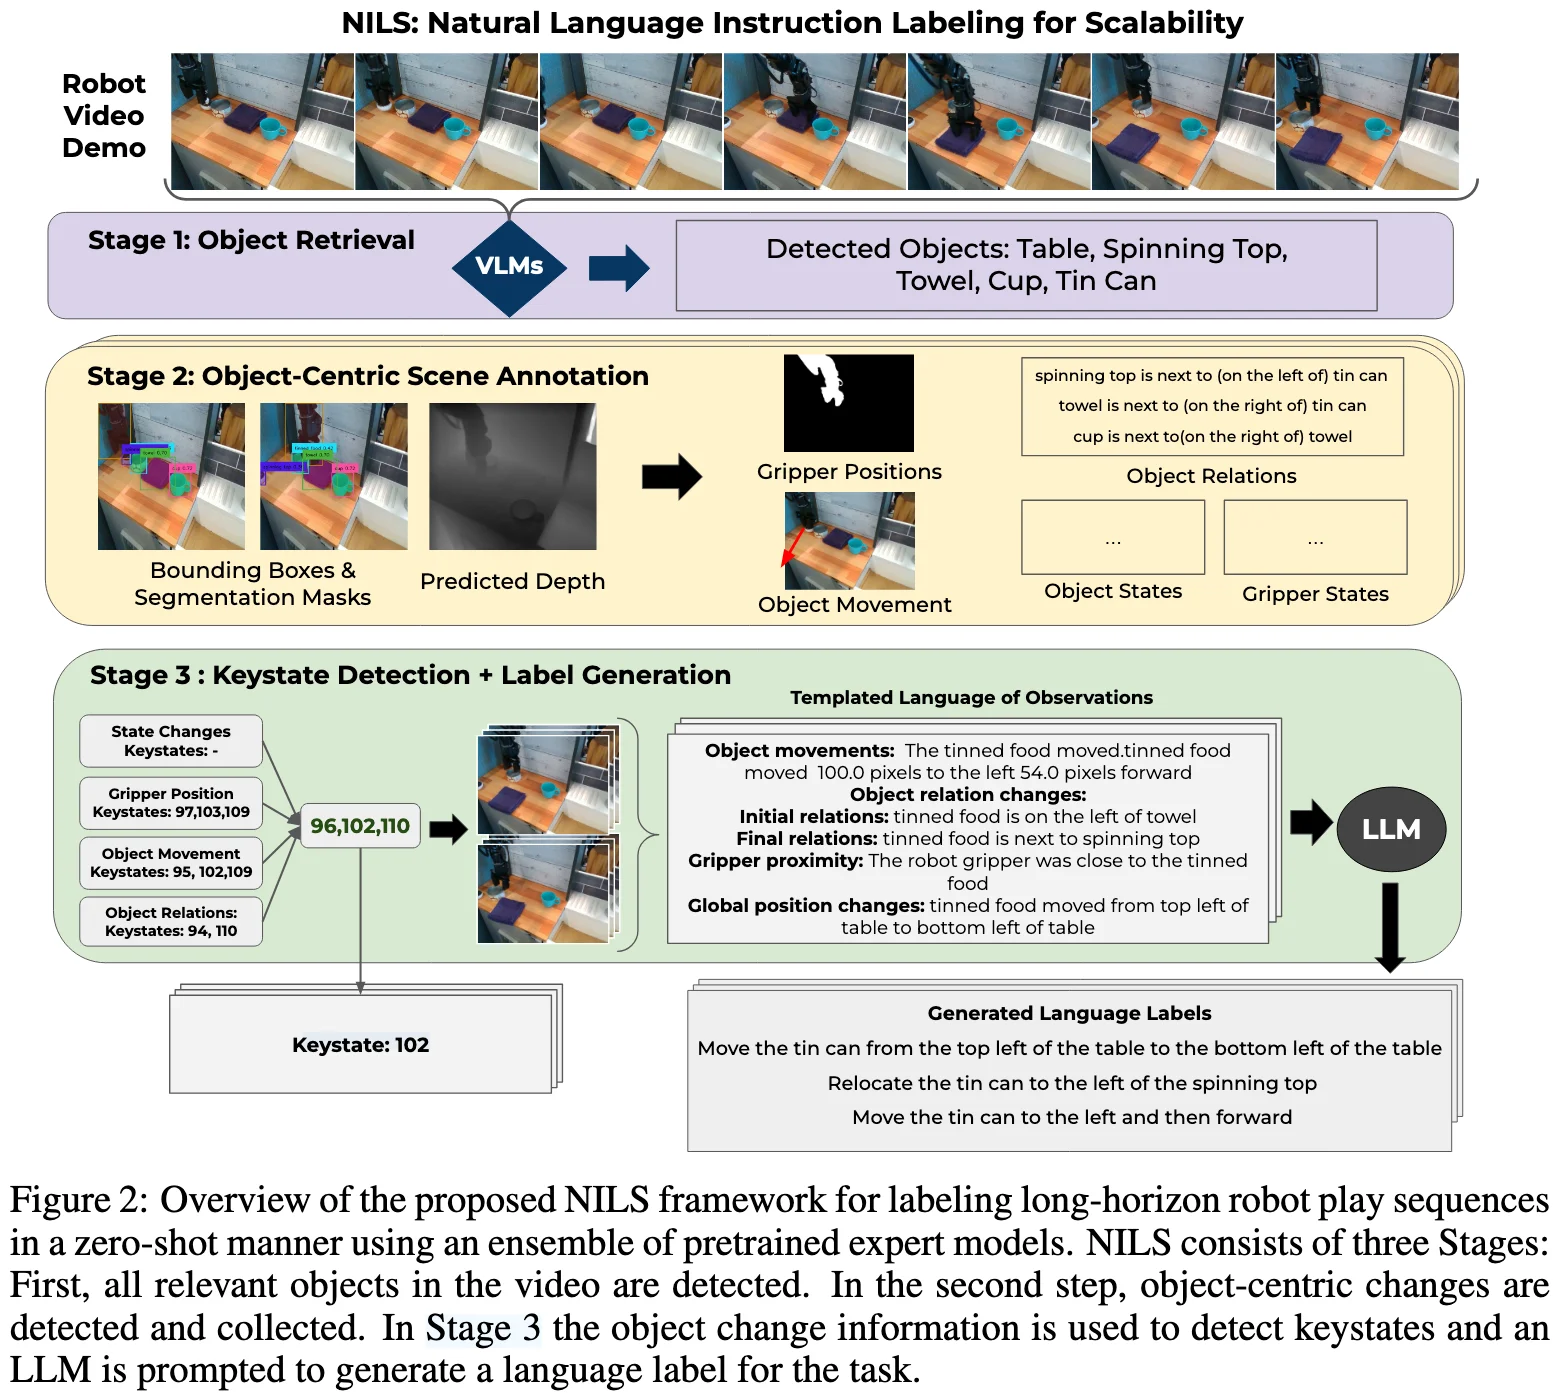
Identifying Objects in the Scene
-> objects and properties.
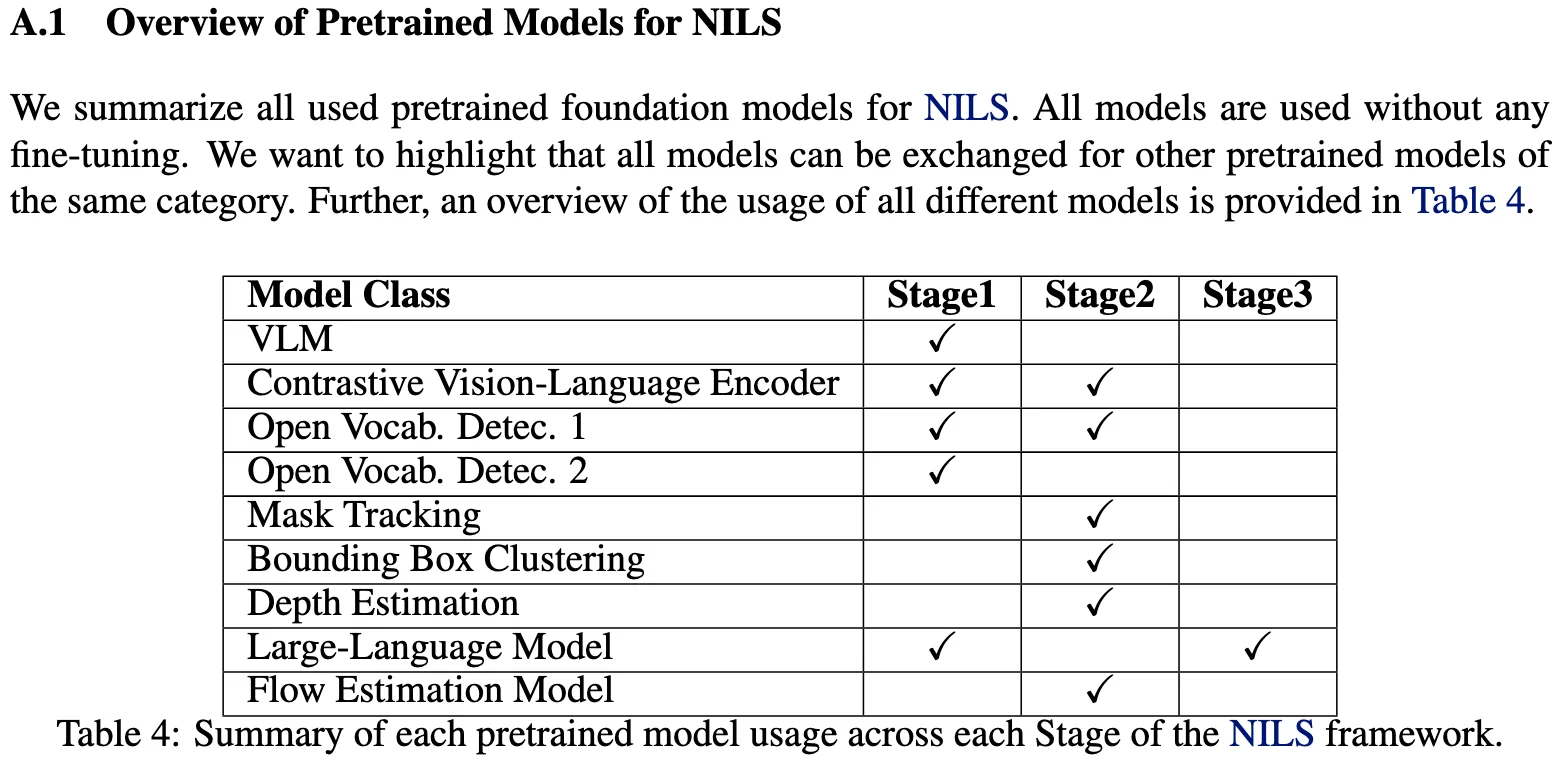
VLMs, Grounding DINO, SigLIP
Object-Centric Scene Annotation
using an ensemble of open-vocabulary detection and segmentation models.
Keystate Detection and Label Generation